Warbixin cusub oo ka soo baxday dacwadda xuquuqda macmal ee New York Times ayaa sheegaysa in Microsoft iyo OpenAI ay ka dhaceen 'dambiyo waaweyn' oo ku saabsan macmal
Warbixin cusub oo ka soo baxday dacwadda xuquuqda macmal ee New York Times ayaa sheegaysa in Microsoft iyo OpenAI ay ka dhaceen 'dambiyo waaweyn' oo ku saabsan macmal, iyadoo la sheegay inay ka dhaceen 'dambiyo waaweyn' oo ku saabsan macmal.
Dacwadda New York Times iyo OpenAI
New York Times ayaa saddex sano ka hor dacwad ku dhiibtay OpenAI iyo Microsoft, iyadoo sheegtay inay ka dhaceen 'dambiyo waaweyn' oo ku saabsan macmal. Warbixinta cusub ayaa sheegaysa inay ka dhaceen 'dambiyo waaweyn' oo ku saabsan macmal.
Warbixinta cusub ayaa sheegaysa inay ka dhaceen 'dambiyo waaweyn' oo ku saabsan macmal, iyadoo la sheegay inay ka dhaceen 'dambiyo waaweyn' oo ku saabsan macmal.
Dacwadda New York Times iyo OpenAI
Warbixinta cusub ayaa sheegaysa inay ka dhaceen 'dambiyo waaweyn' oo ku saabsan macmal, iyadoo la sheegay inay ka dhaceen 'dambiyo waaweyn' oo ku saabsan macmal.
Warbixinta cusub ayaa sheegaysa inay ka dhaceen 'dambiyo waaweyn' oo ku saabsan macmal, iyadoo la sheegay inay ka dhaceen 'dambiyo waaweyn' oo ku saabsan macmal.
Dacwadda New York Times iyo OpenAI
Warbixinta cusub ayaa sheegaysa inay ka dhaceen 'dambiyo waaweyn' oo ku saabsan macmal, iyadoo la sheegay inay ka dhaceen 'dambiyo waaweyn' oo ku saabsan macmal.
Warbixinta cusub ayaa sheegaysa inay ka dhaceen 'dambiyo waaweyn' oo ku saabsan macmal, iyadoo la sheegay inay ka dhaceen 'dambiyo waaweyn' oo ku saabsan macmal.
New unredacted details from a three-year-old copyright lawsuit reveal that a top Microsoft executive privately described the companies' AI training practices as theft, while OpenAI's own leaders warned that their models pose an existential threat to publishers.
Internal Admissions of Harm and Market Substitution
Microsoft's own data shows its Copilot answer engine caused click-through rates for The New York Times to drop as much as 93% compared to traditional Bing search. An internal presentation by Brent Hecht in January 2024 described the decline as a doom loop that would hurt model performance and the entire web simultaneously.
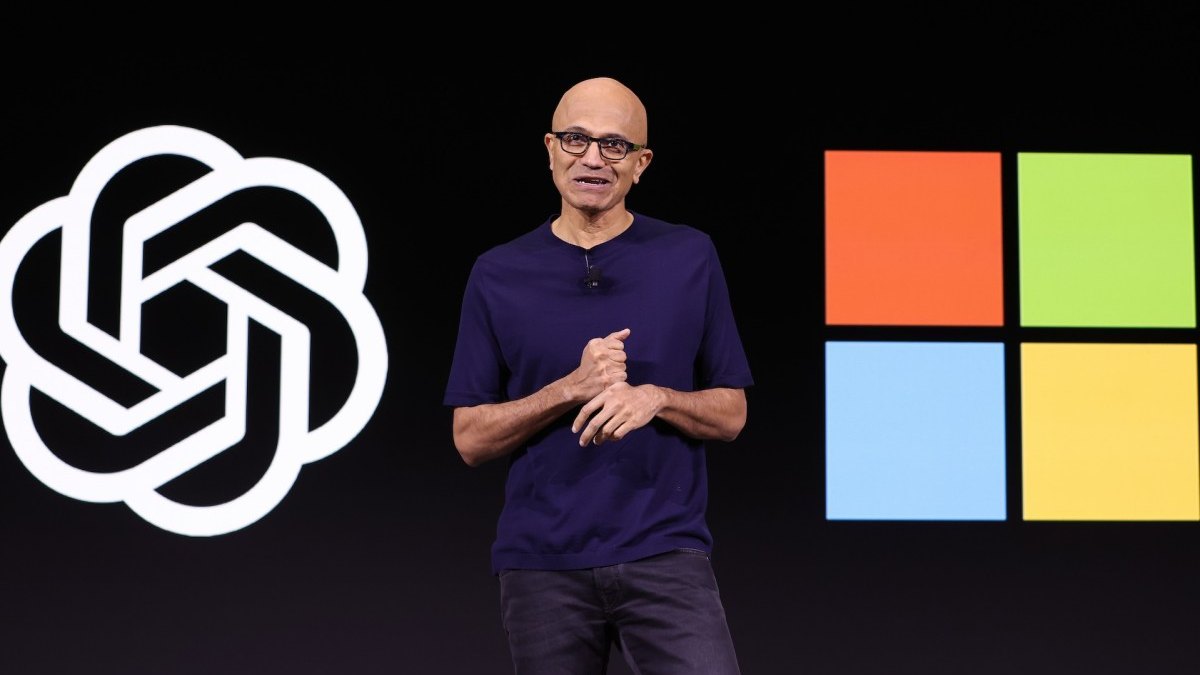
Microsoft CEO Satya Nadella testified in a deposition that anything paywalled should be licensed by anyone who wants to use it for training. He added that if he had known OpenAI scraped paywalled content, he would have invoked Microsoft's right to require OpenAI to retrain its models.
Scale of Scraping and Deliberate Circumvention
OpenAI's mid-training datasets alone contain more than 91,692 copies of works published by the NYT, Daily News, and Center for Investigative Reporting. A Common Crawl-derived dataset included more than 2 million documents from nytimes.com alone, with Project Mango data containing at least 160,903 unique works from news publishers.
The filings describe how OpenAI researcher Nick Ryder told Greg Brockman about a hack to get around the nytimes paywall, to which Brockman replied: ah nice. Employees also built datasets like WebText and WebText2 that disproportionately relied on scraped news content, while deliberately stripping copyright notices from training data.
Legal and Political Dimensions of the Dispute
OpenAI's Head of ChatGPT, Nick Turley, wrote that publishers face an existential threat from products that are largely substitutive and will get more substitutive as they improve. OpenAI President Greg Brockman described the models as excellent at news, while a Microsoft document warned of a real risk that generative AI could significantly disrupt the employment of the very people who generated the training data.
The question of whether AI firms can legally use copyrighted material to train AI has no clear answer, though judges have been largely favorable to AI companies' fair use arguments. Earlier this month, the Trump administration contributed a brief in defense of OpenAI's unlicensed use of copyrighted material to train its large language models.
Ilaha iyo xuquuqda sawirka
Sawir: TechCrunch Xigasho